


Router Settings
Two ways to ask for a model. Name one and nRouter never swaps it, or send nrouter/auto for Best for the task or Lowest cost. Set fallbacks and caching too.
Router Settings (/router-settings) sets how an organization's requests are routed: fallbacks for named models, retry limits, response caching, and how nrouter/auto chooses a model. Owner and Organization Admin roles can change it; everyone else has read-only access. New here? Set up routing walks through the setup in five minutes.
Two ways to ask for a model
Two ways to ask for a model. Direct — you name the model, and nRouter never swaps it for another; a different model answers only through a fallback you configured yourself, and only when the provider cannot take the request. nrouter/auto — nRouter chooses an eligible model for you, by the preference below. Either way, you pay the served model's list price, and x-nr-model names the model that answered.
Router Settings has two pages:
- Direct (
/router-settings): fallback lists for named models, retry limits, wait budgets, and response caching. nrouter/auto(/router-settings/auto): the preference below, and whether new models join automatically. The per-model on/off switches live in Model Catalog → nrouter/auto (/model-catalog/auto), not here.
Withdrawn: Smart Routers and Per-Model Weights were withdrawn on 2026-10-15; requests naming withdrawn aliases return the unknown-model error.
nrouter/auto: the two preferences
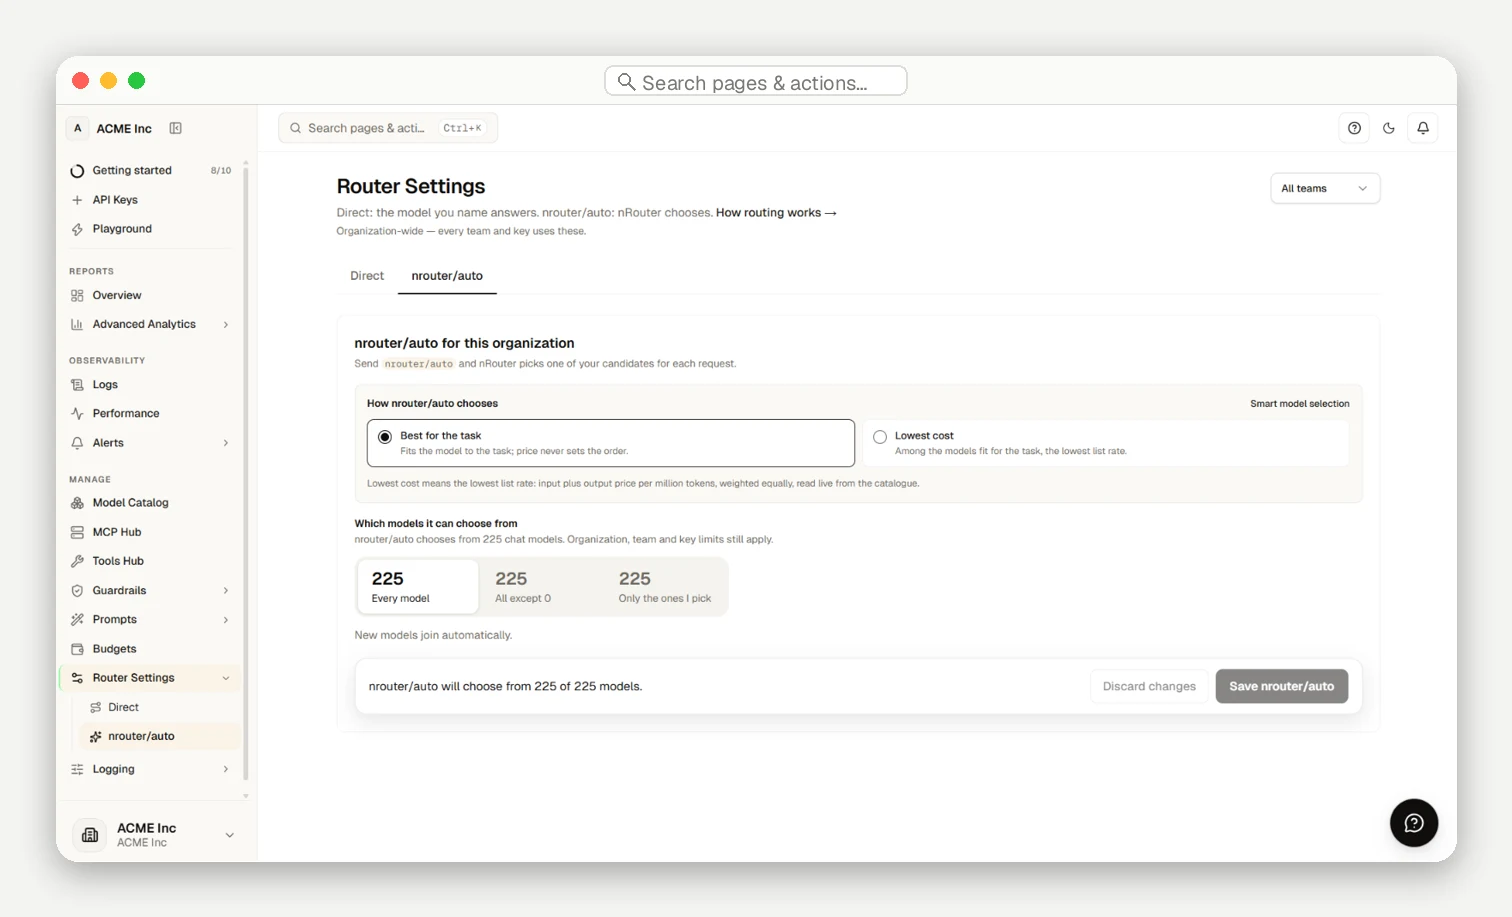
The preference is an organization-wide setting on the nrouter/auto page of Router Settings, changed by an Owner or Organization Admin. Best for the task is the default, and nothing in your code changes: every request still sends nrouter/auto.
| Preference | How the model is chosen |
|---|---|
| Best for the task (default) | A decision model, TypeSafe Jev System One, chooses under a 2,000 ms decision deadline. If it gives no accepted answer in that time, the reviewed default model for the request's tier serves it. |
| Lowest cost | Picks the capable candidate with the lowest estimated request cost within the active cost band (low under $1, mid $1 to under $7 by default, or high $7+ per million tokens on the (3 * input + 1 * output) / 4 blended list rate read live from the catalogue). On abstain, low confidence, timeout, or when Smart model selection is off, the reviewed Default Pick within the active cost band serves the call. |
Every allowed model is a candidate by default; if every model is off, the gateway refuses with a pre-hold 503. Fit for the task: Three signals mark a request as heavy — reasoning is asked for, the input is long, or the request carries tools and has passed the agentic-turn threshold — and a heavy request is offered heavy models only. The requested output cap (max_tokens) does not choose the tier. Turn off Smart model selection under Settings → Privacy to ensure the prompt is never sent to the decision model — Best for the task may then refuse with a 400 naming the setting, while Lowest cost serves the Default Pick from request signals alone without sending prompt text to the decision model. Per call, nrouter_optimize: "quality" or "cost" overrides the saved preference, and under "cost" you can set nrouter_cost_band: "low" | "mid" | "high" (Per-Request Options).
Choosing Lowest cost and cost bands
Select Lowest cost on the nrouter/auto page of Router Settings, or pass "nrouter_optimize": "cost" on a request. Under Lowest cost, nrouter_cost_band sets an "at most" ceiling using each model's (3 * input + 1 * output) / 4 blended list rate per million tokens:
"low"— models under$1per million tokens (lowband only)."mid"(default) — models from$1to under$7per million tokens (admitslowandmid)."high"— models at$7+per million tokens (admitslow,mid, andhigh).
curl https://api.nrouter.ai/v1/chat/completions \
  -H "Authorization: Bearer $NROUTER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model": "nrouter/auto", "nrouter_optimize": "cost", "nrouter_cost_band": "low", "messages": [{"role": "user", "content": "Hello!"}]}'
If the active cost band leaves zero eligible models after applying access lists, organization auto-model policy, context/output limits, required capabilities, endpoint support, health, and positive pricing, the gateway refuses with 400 cost_band_unsatisfiable at $0 before placing a credit hold — the band never escalates. Sending nrouter_cost_band on a Direct model call, with an unrecognized value, or under "quality" returns 400 invalid_request. Under "cost", a request nrouter_fallbacks entry whose blended rate exceeds the active nrouter_cost_band ceiling returns 400 fallback_not_allowed (organization-saved fallbacks outside the band are skipped).
Fallbacks and retries
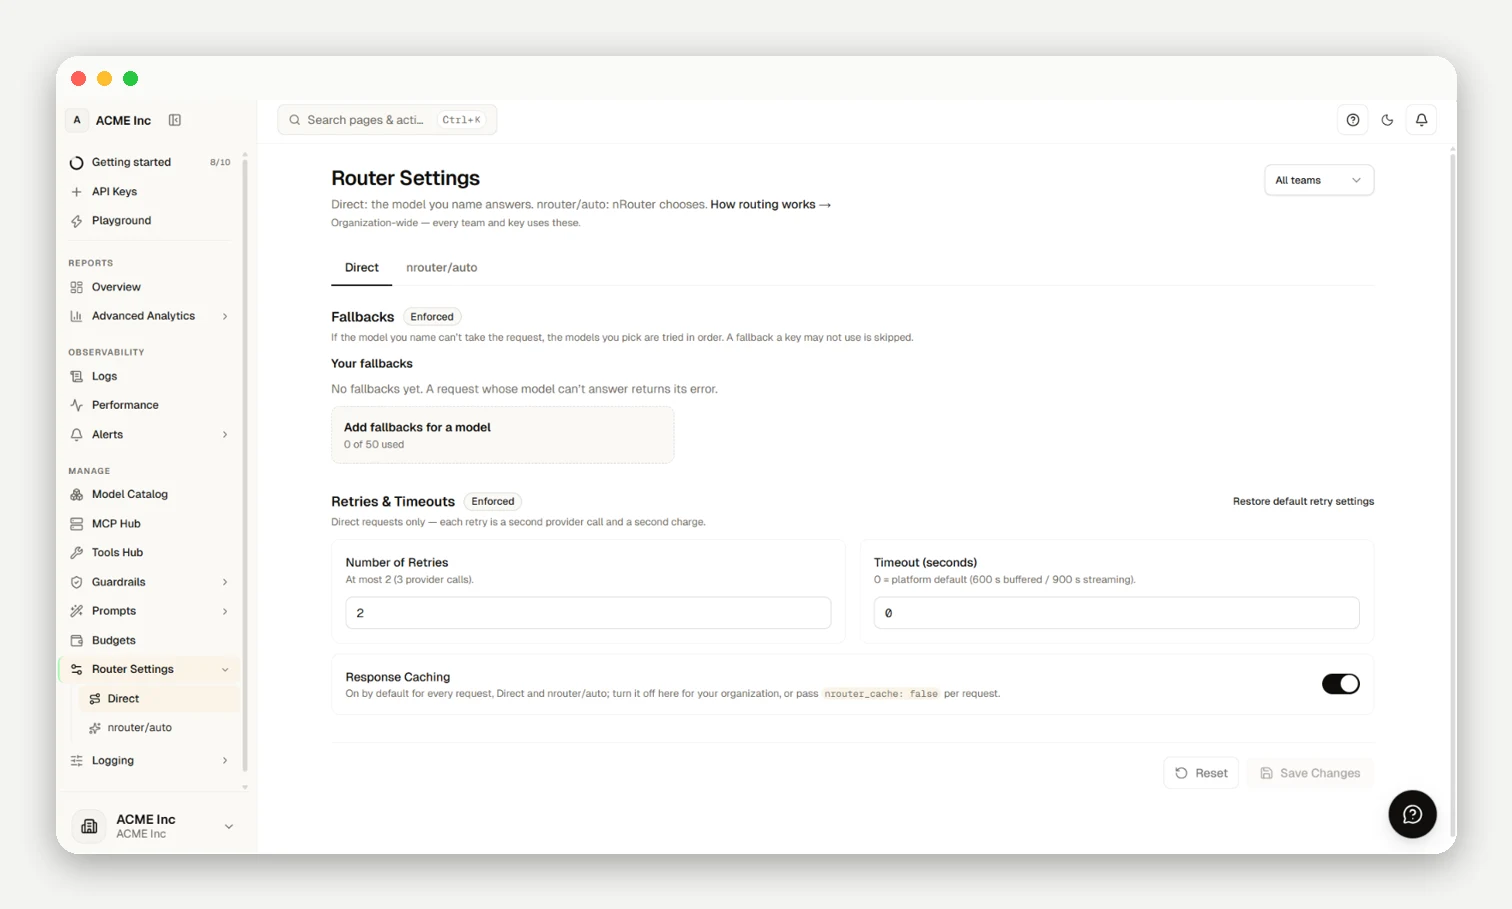
A fallback is tried only when the provider cannot take the request: an upstream 429, 503 or Anthropic 529, a 401 or 404 from a misconfigured provider deployment, a connection that never opened, or a provider that sends no first byte in time. A 500, 502, 504, or any error after response bytes arrive, is returned as-is, never moved. One credit reservation and one rate-limit slot cover the whole chain; override the saved lists per call with nrouter_fallbacks — on nrouter/auto it replaces the fallbacks nrouter/auto would choose; inaccessible targets return 400 fallback_not_allowed.
Retries allow at most 3 provider attempts within a 20-second wait budget, on Direct requests only; nrouter/auto runs its own bounded 3-attempt loop. Response caching is on by default (Response Caching). Every response reports x-nr-model, x-nr-routing (direct or fallback:<n>) and x-nr-attempts — the last two absent on cache hits and refusals. Changes take effect immediately, with no redeployment.
Frequently asked questions
Who on my team can change router settings?
Owners and Organization Admins manage organization-wide settings; Team Admins manage team allowlists; Members have read-only access.
What is the difference between Best for the task and Lowest cost?
Best for the task uses smart model selection when it is available: a decision model chooses the model for the task under a 2,000 ms decision deadline, while Lowest cost picks a capable model with the lowest estimated request cost within the active cost band (low under $1, mid $1 to under $7 by default, or high $7+ per million tokens on the (3 * input + 1 * output) / 4 blended list rate) and serves the Default Pick on abstain, timeout, or Smart model selection opt-out.
Does Lowest cost guarantee the smallest bill?
No, because estimated request cost uses prompt size and the requested output cap before generation begins, whereas final settlement bills the actual input and output tokens at the served model's list price.
What happens when a model fails mid-request?
Failovers trigger only on an upstream 429, 503 or Anthropic 529, a 401 or 404 from a misconfigured provider deployment, a connection that never opened, or a provider that sends no first byte in time; upstream 500, 502, 504 or post-first-byte errors return as-is.