

Company
Four Outcomes That Get an LLM Gateway Funded
Build the internal business case for an LLM gateway on four quantifiable outcomes: total spend reduction, cost per call, tail latency, and developer speed.
nRouter team
10 minRead →As enterprise generative AI deployments expand from departmental experiments to core production infrastructure, unmanaged token consumption can quickly derail engineering budgets and profitability. LLM FinOps applies financial operations rigor to AI tokenomics, establishing multi-tenant budget ceilings, granular cost attribution tags, automated 3-way invoice reconciliation, and automated prompt compression to guarantee positive unit economics across all AI initiatives.
Autonomous AI agents running recursive tool-calling loops can trigger hundreds of unexpected API calls in seconds, causing rapid budget depletion without strict circuit breakers and spend controls.
Shared master API keys obscure which internal teams, products, or end-customers generate costs, preventing accurate margin analysis and per-user chargebacks across corporate departments.
Complex token pricing structures—differentiating between cached inputs, prompt tokens, completion tokens, and image generation—make invoice verification error-prone and labor-intensive.
Bloated system prompts, verbose RAG document chunks, and chat history accumulation unnecessarily consume context windows and drive up inferencing fees across model families.
3-way automated matching across provider billing, internal spend ledgers, and customer invoices.
Sidecar compression reducing prompt token counts by up to 50% while preserving semantic fidelity.
Deterministic pre-execution credit holds and hard caps enforced at org, team, and virtual key levels.
nRouter provides comprehensive FinOps capabilities designed specifically for large language model workloads. With FOCUS 1.4 compliant spend accounting, nRouter reconciles provider costs against real-time request logs, detecting billing anomalies and margin leaks immediately. Organizations configure granular spend limits and rate ceilings per virtual key, team, and organization. By combining automated prompt compression via LLMLingua-2 with Strategy::Intent routing and zero per-token markup, nRouter reduces total token spend while providing full cost attribution.
Read our FinOps playbooks to master token budgeting, implement internal chargeback models, and achieve sustainable AI gross margins.
Build the internal business case for an LLM gateway on four quantifiable outcomes: total spend reduction, cost per call, tail latency, and developer speed.
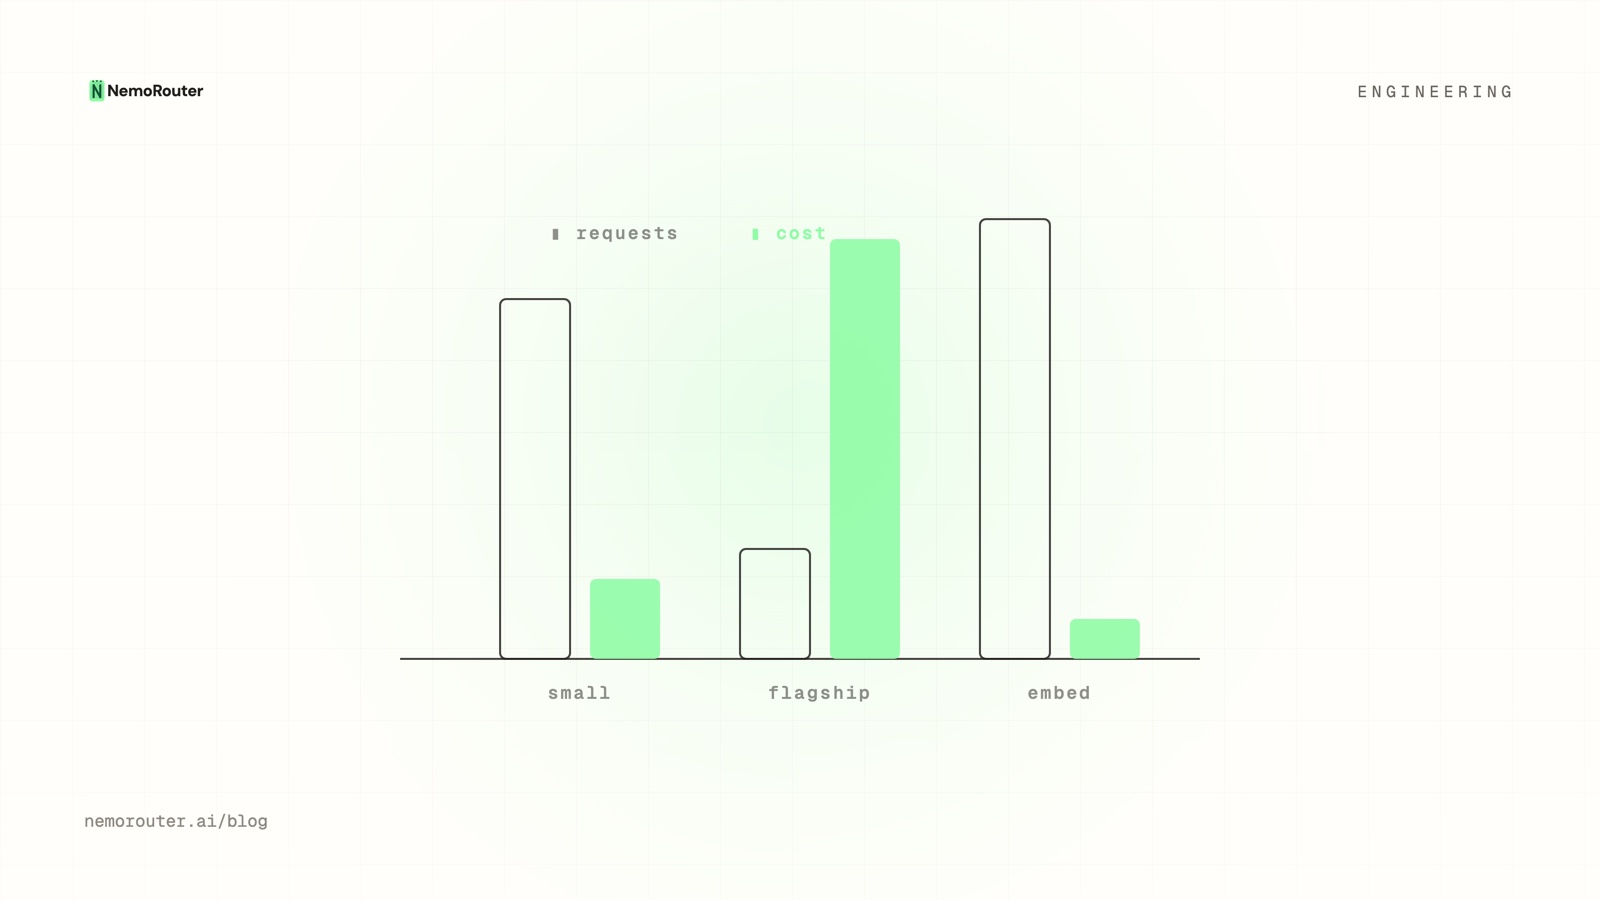
Request count and dollar cost tell different stories, and the gap between them is where the savings are. Here are the four shapes an overlay of cost and usage produces, which one to chase first, and what makes the numbers trustworthy enough to act on.
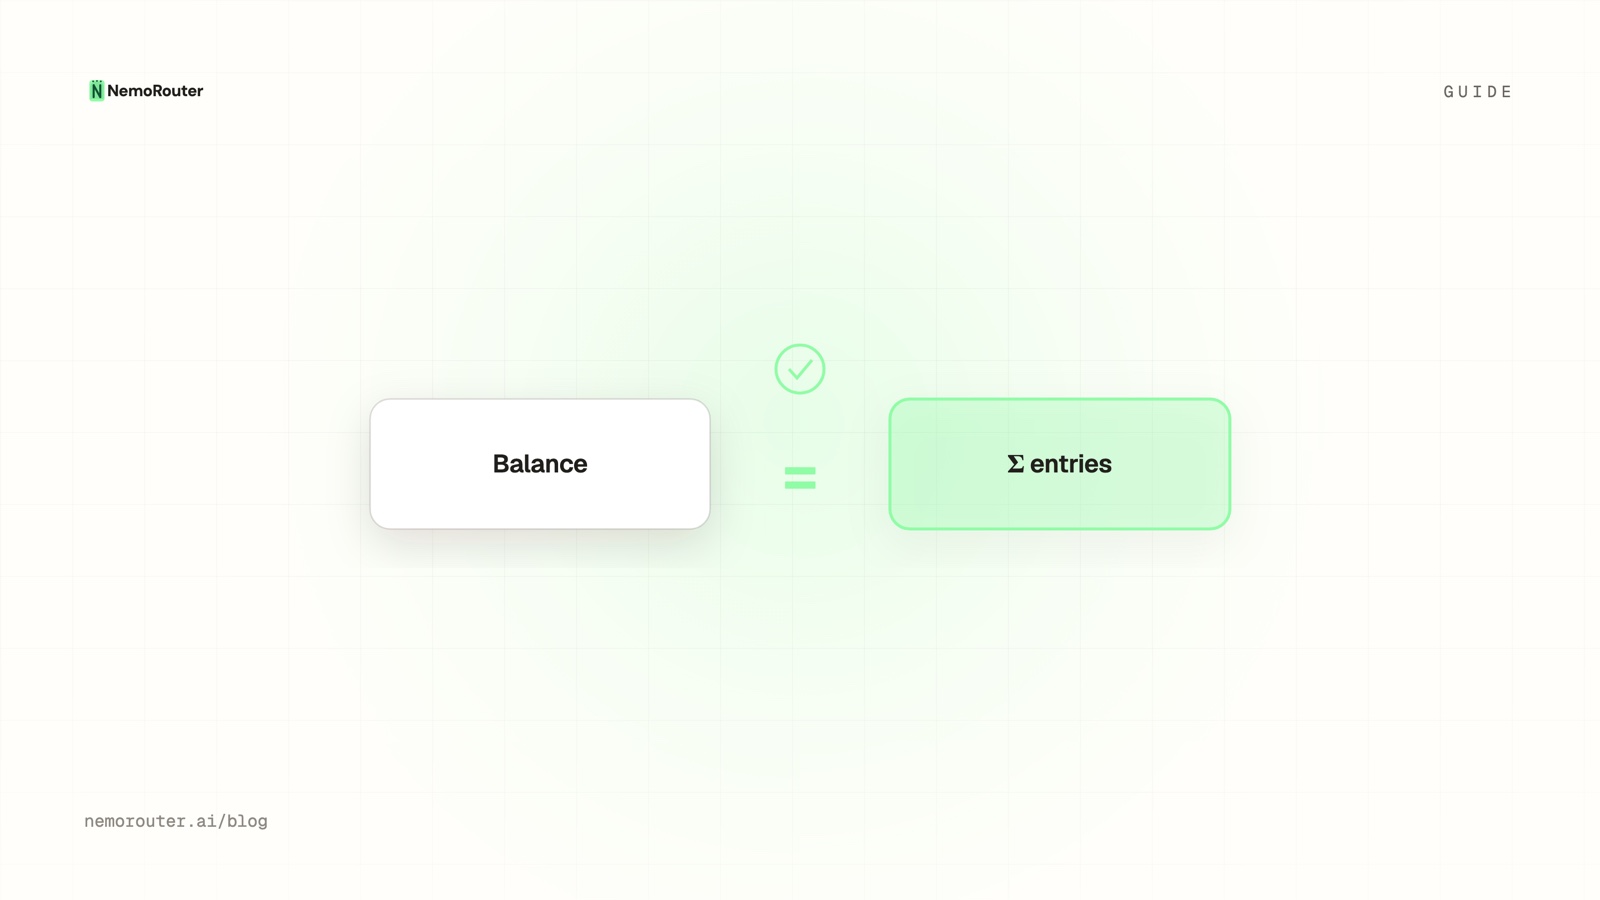
Your balance is not a stored number, it is the sum of a ledger. Here is how to read the four numbers on the balance card, the entry types behind them, and the two identities that prove your balance is doing what it should.
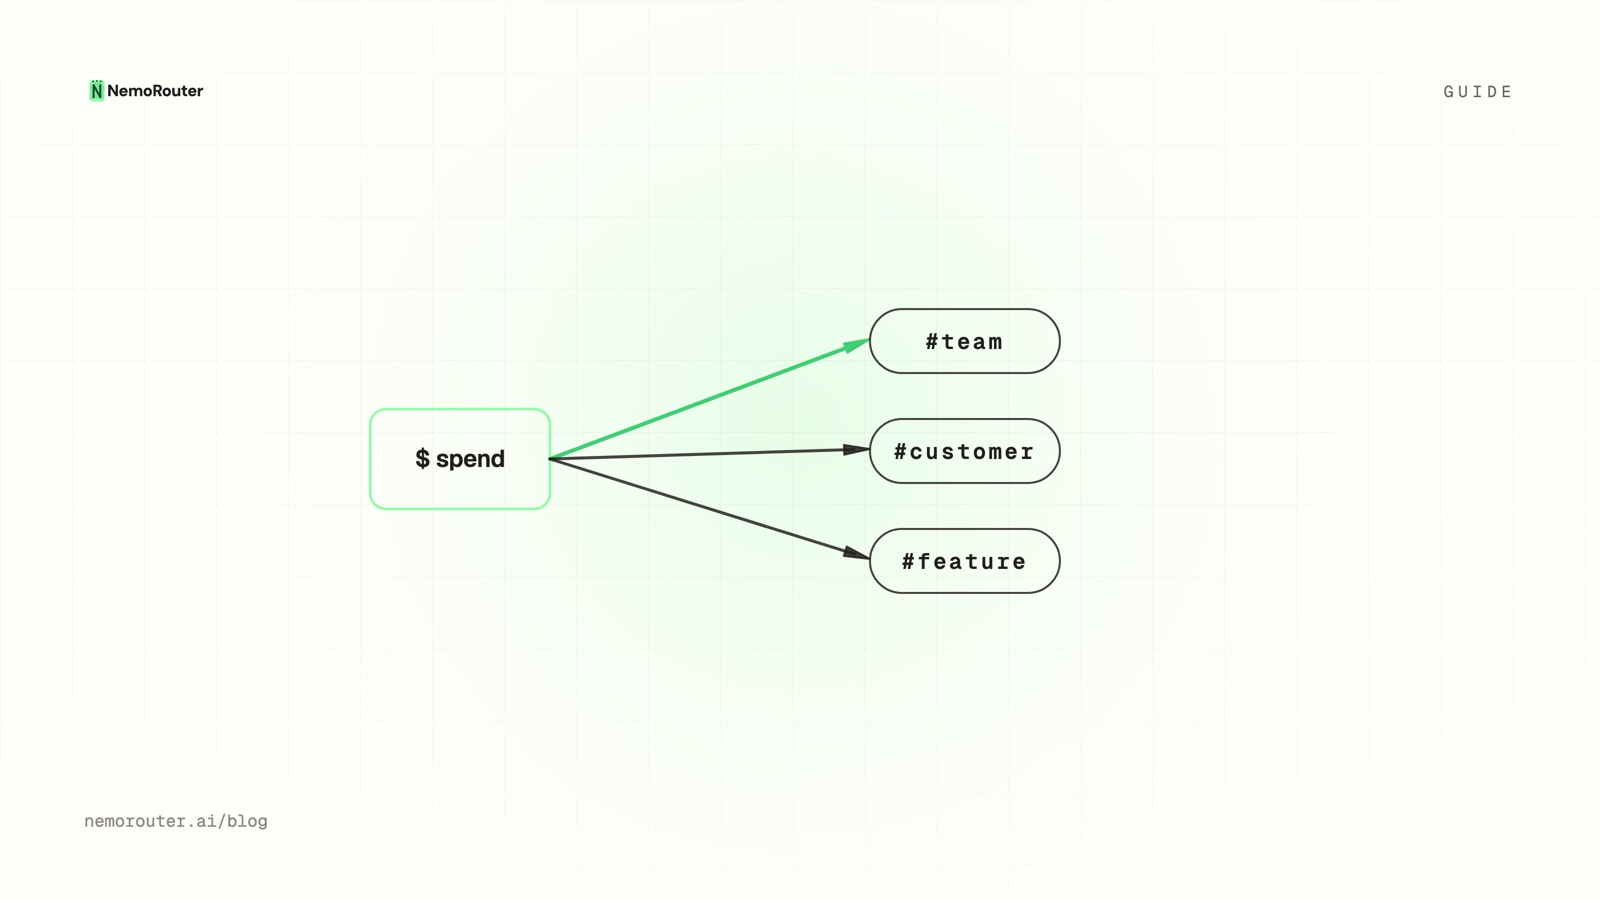
"The AI bill went up" becomes a query once spend carries structure. Three attribution layers — virtual keys, teams, and the OpenAI-spec user field — turn one opaque total into a breakdown you can group, filter, and cap.
If you resell AI, the model bill is the wrong unit. Attribute every call to the customer it served with the OpenAI user field, cap each customer independently, and reconcile the sum against your ledger to the cent.
Provider pricing does not normalize on its own — per-token, per-image, per-second, provisioned. Here is how nRouter turns that into one settled cost per request that your app, your ledger and your dashboard all read, and why an unknown cost is reported as absent rather than as zero.