Server-Side Prompt Templates: Version, Roll Back, A/B Test
Reference server-side prompt templates by ID instead of inlining them: update prompts without deploys, roll back instantly, and A/B test on live traffic.
Selecting the optimal foundation model requires empirical evaluation under live production traffic. Deterministic A/B testing enables engineering teams to evaluate prompt variations, quantization levels, and competing model providers simultaneously without rewriting application code. By splitting traffic based on consistent user hashing, teams evaluate latency, output quality, and cost trade-offs statistically before committing to full migrations.
Randomized traffic routing causes individual users to receive oscillating responses and formatting inconsistencies across consecutive conversation turns, degrading user experiences.
Hardcoding model comparisons into application code requires full deployment cycles to adjust split percentages or test new candidate models under production conditions.
Evaluating models across fragmented dashboards prevents direct side-by-side analysis of p95 latency, cost per thousand tokens, and failure rates across competing vendors.
Quantifying qualitative improvements between frontier models requires automated LLM-as-a-judge scoring pipelines and user feedback correlation across production datasets.
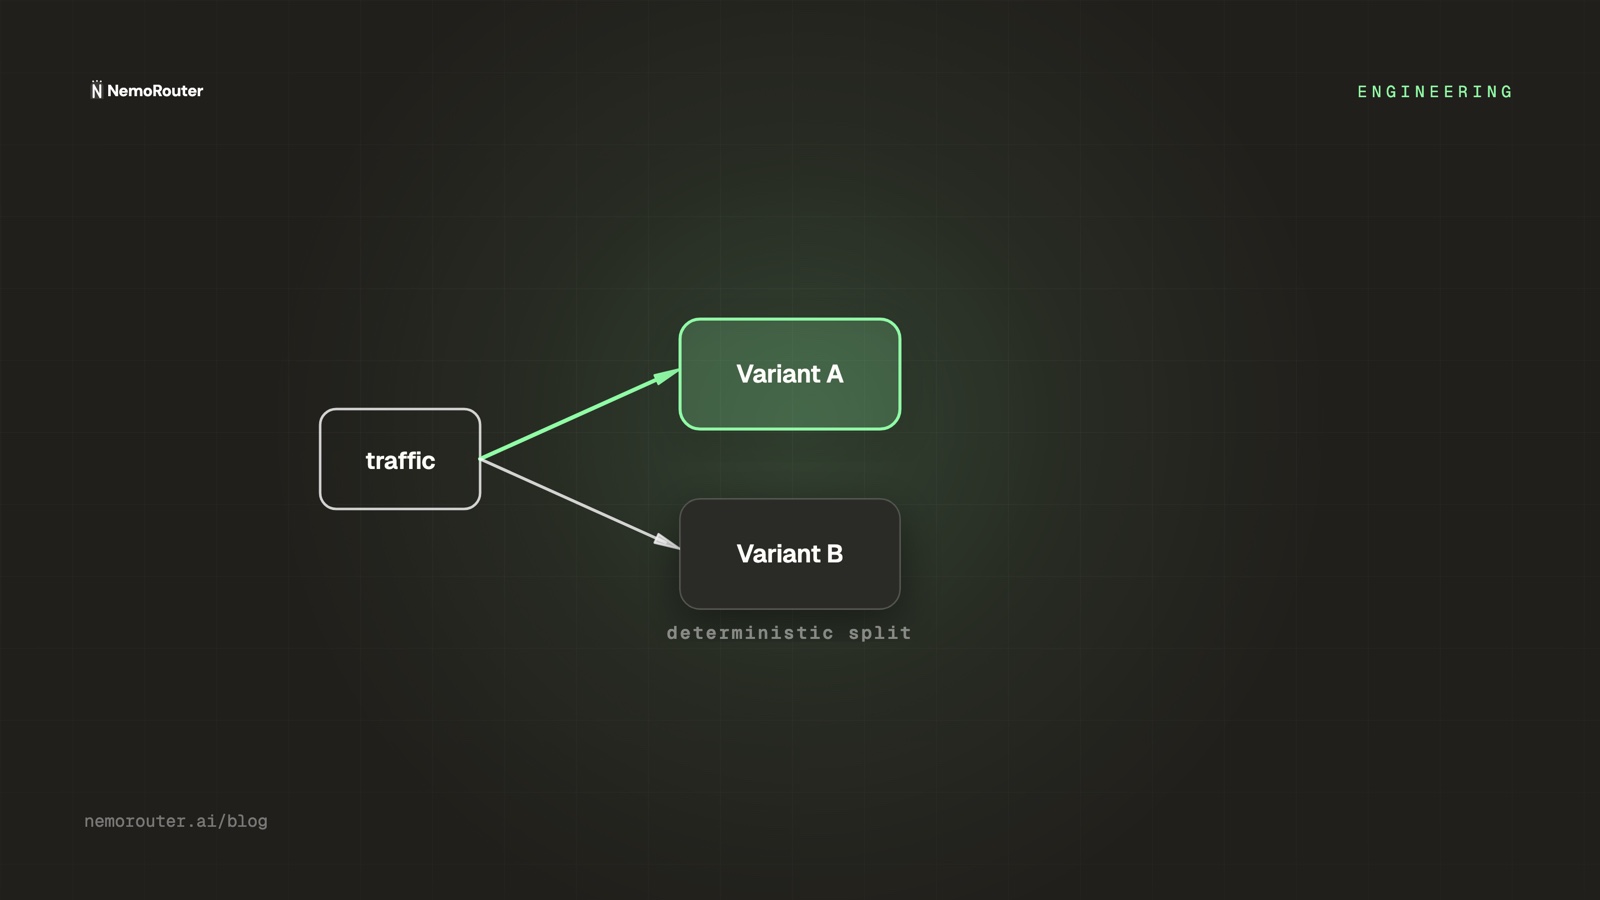
Deterministic traffic distribution using MurmurHash3 on user ID or conversation session key.
Real-time telemetry dashboard comparing TTFT, total latency, spend, and error rates per variant.
Adjust traffic split percentages dynamically across models without restarting gateway services.
nRouter provides deterministic, gateway-level A/B testing for models and prompt templates. Using consistent hashing over customer identifiers or session tokens, nRouter guarantees that individual users interact with the same model variant throughout their session. Configure multi-variant splits (e.g. 50% Claude 3.5 Sonnet vs. 50% GPT-4o) with dynamic weighting. The unified observability canvas tracks side-by-side performance metrics—latency percentiles, exact cost differentials, and error rates—allowing data-driven model selection without application code changes.
Read our guides on running production model benchmarks, structuring statistical evaluations, and executing zero-downtime model migrations.

Reference server-side prompt templates by ID instead of inlining them: update prompts without deploys, roll back instantly, and A/B test on live traffic.

Quality is a property of a task, not of a model. Here is how to inventory your traffic by task, point a router alias at a candidate set, prove each downgrade with an A/B test, and read the saving off the Cost vs Usage report.

A coin flip on every request is not an experiment — it is noise with a dashboard. Here is how deterministic hash-based assignment gives each user a stable variant for the life of a test, why the experiment id belongs in the hash, and what the gateway refuses to let a caller override.

Not Diamond returns a model recommendation and charges $0.05 per million tokens routed — you still hold every provider key and make the call yourself. What that leaves you to build, and how deterministic A/B tests compare to a trained router when you have to reproduce a decision.

nRouter vs Unify AI for teams weighing benchmark-driven model arbitration against operator-pinned routing. Why a vendor leaderboard is not your eval, and how to compute cost-per-passing-answer from your own requests.