The Enterprise LLM Gateway,
Built for Production Workloads.
One key for every model. Sub-millisecond smart routing, guardrails and hard budgets.
Requests from your chat apps, agents, RAG pipelines and SDKs pass security checks, then the nRouter gateway applies guardrails, routing and budgets before calling the model you asked for. Requests blocked before reaching a provider hold and spend $0.
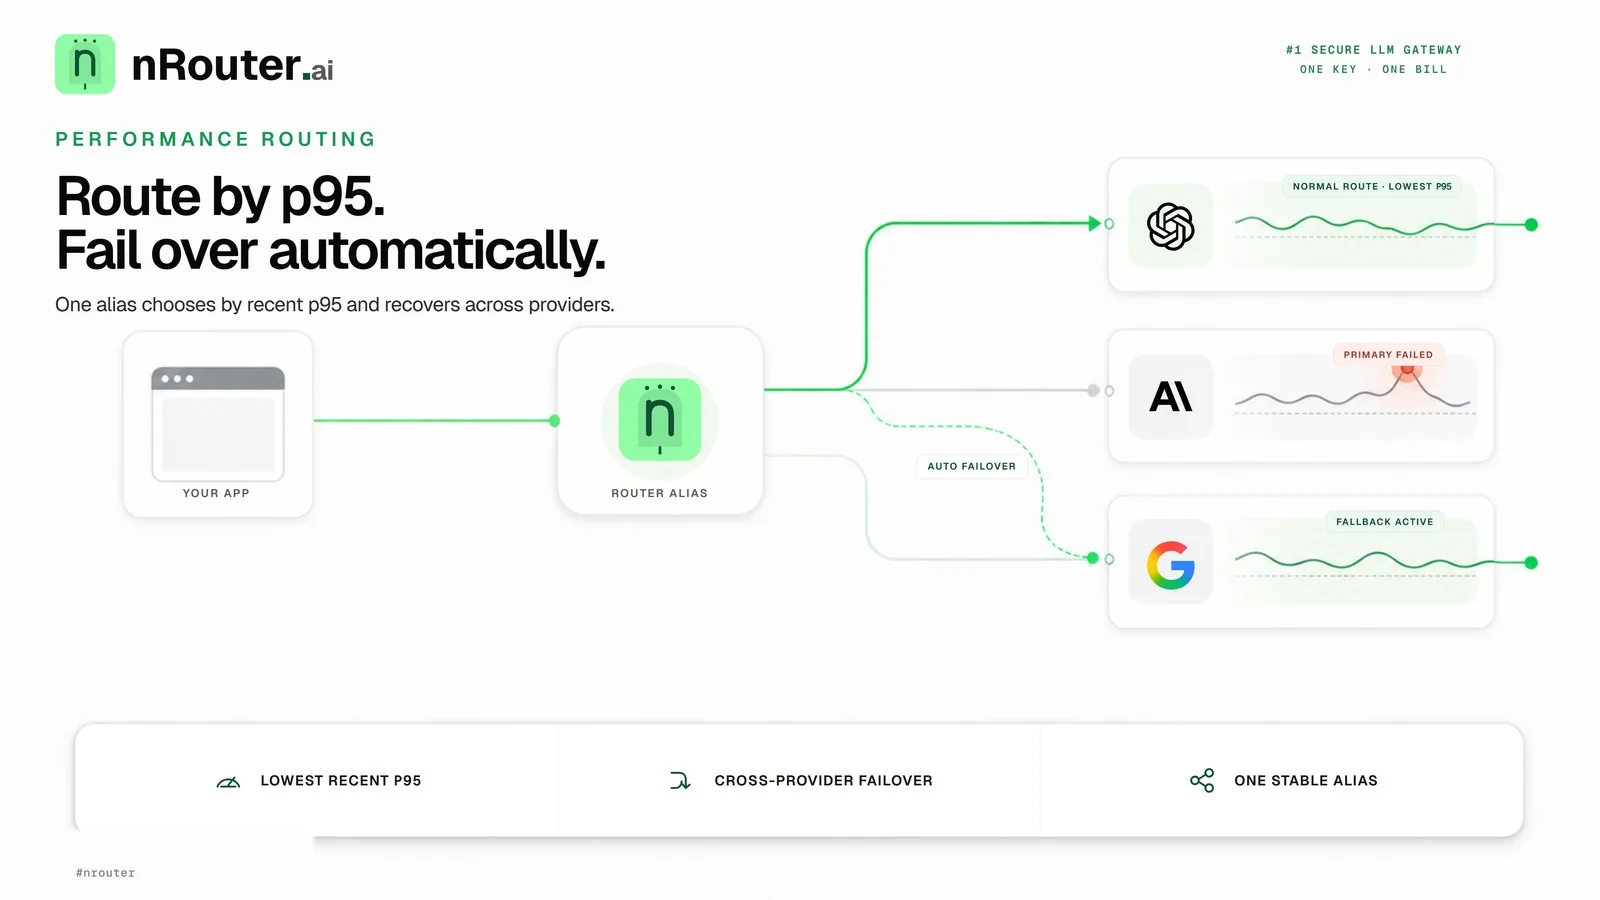
Coloured requests route in from the dark and ignite the nRouter mark, then the architecture: apps send one request through a security check to api.nrouter.ai, which applies guardrails, routing and budgets before calling OpenAI, Anthropic, Google or Azure Foundry models. Then an SDK call with its exact cost, a prompt injection blocked before any provider at $0, and a stalled provider replaced by the next model, billed only for the one that answered; nrouter/auto reading each task and picking its model; every request with its route and exact cost; and a key whose budget is spent, refused at the gateway at $0.
Pay only for what you use. No platform fee — save 5.5% on every top-up.
Maker-reported reasoning score
GPT-6 Astra
Try itResponse cache is on automatically
Platform fee$0.00
You save ≈ $55 vs a 5.5% top-up fee
One gateway. Routing, safety and spend controls.
Latest articles



How it works
- sk-nrouter-••••••••4f2a
Shown once. Stored as a hash.
- $ pip install nrouter-sdk
Start building
Quickstart guidefrom nroutersdk import nRouter client = nRouter() res = client.chat.completions.create(model="gpt-5", messages=[{"role": "user", "content": "Hello, world!"}]) print(res.choices[0].message.content)